Ask an engineering team what they run in production and you will rarely hear the name of the model that topped last month's leaderboard. You hear about a smaller model, pinned to a version, wrapped in caching, doing one narrow job well. The gap between what gets written about and what gets deployed has never been wider.
That gap exists because the two are judged on different scoreboards. Frontier models are judged on capability ceilings. Production models are judged on cost per resolved request, and those numbers pull in opposite directions once you serve anything at volume.
Small language models vs LLMs: what actually differs
"Small" is relative. In a hosted model family it usually means the fastest, cheapest tier. For open models it often means something that fits on one GPU, or even a laptop. Either way, the trade looks the same.
| Small language model | Large (frontier) model | |
|---|---|---|
| Cost per token | Lowest tier, often 4x to 10x cheaper | Highest tier |
| Latency | Fast, good for real-time UX | Slower, especially with long reasoning |
| Strong at | Classification, extraction, formatting, short answers with context | Ambiguous requests, multi-step reasoning, novel problems |
| Weak at | Open-ended reasoning, thin or missing context | Nothing in particular, except cost at volume |
| Best use | The routine majority of requests | The hard or high-stakes minority |
What LLM inference actually costs
Price differences between tiers are large enough to change architecture decisions. Here are Anthropic's list API prices as a reference point; other providers show a similar spread between their small and large tiers.
| Model tier | Input per MTok | Output per MTok | Relative input cost |
|---|---|---|---|
| Claude Haiku 4.5 (small) | $1 | $5 | 1x |
| Claude Sonnet 5 (mid) | $2 | $10 | 2x |
| Claude Opus 5.5 (large) | $4 | $20 | 4x |
| Claude Fable 5.1 (frontier) | $10 | $50 | 10x |
Prices are from Anthropic's pricing page (opens in a new tab) and change often, so check before you budget. Batch processing halves both input and output prices for work that does not need an instant answer, and prompt caching makes repeated context, such as a long system prompt, far cheaper on every call after the first.
A worked monthly cost example
Take a support assistant handling 400,000 conversations a month. Each conversation averages six turns, each turn sends about 2,000 tokens of context and gets about 150 tokens back. That is 4.8 billion input tokens and 360 million output tokens a month, before any business logic.
| Setup | Input cost | Output cost | Monthly total |
|---|---|---|---|
| Everything on the large model (Opus 5.5) | $19,200 | $7,200 | $26,400 |
| Everything on the mid model (Sonnet 5) | $9,600 | $3,600 | $13,200 |
| Everything on the small model (Haiku 4.5) | $4,800 | $1,800 | $6,600 |
| Routed: 85% small, 15% large | $6,960 | $2,610 | $9,570 |
The routed setup costs about 64 percent less than sending everything to the large model, and it keeps the large model on the conversations most likely to need it. Running everything on the small model is cheaper still, but that is usually where quality drops and the savings get eaten by retries, escalations and refunds.
How LLM routing works
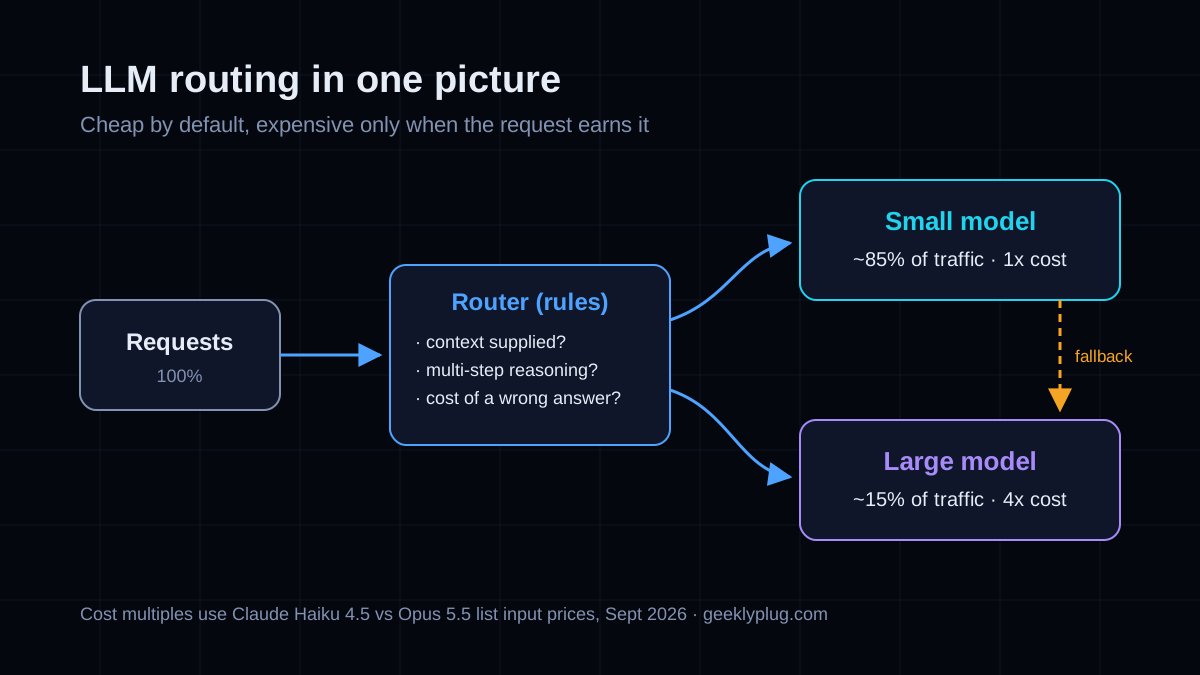
Most request volume in a real product is routine: classification, extraction, reformatting, short answers with a retrieved document already in context. A small model handles those well. The interesting minority is where you spend: ambiguous intent, multi-step reasoning, anything where being wrong is expensive.
type Tier = "small" | "large";

type Task = {
  hasRetrievedContext: boolean;
  expectedTokens: number;
  requiresMultiStepReasoning: boolean;
  errorCostUsd: number;
};

function route(task: Task): Tier {
  if (task.requiresMultiStepReasoning) return "large";
  if (task.errorCostUsd > 50) return "large";
  // Long answers with no supplied context lean on broad knowledge.
  if (!task.hasRetrievedContext && task.expectedTokens > 800) return "large";
  return "small";
}
The router does not need to be clever. A handful of deterministic rules over metadata you already capture gets most of the benefit. Add a fallback so that when the small model's answer fails a validation check, or it signals low confidence, the request is retried on the large model. That single fallback protects quality while the rules do the saving.
Published research backs the approach. The RouteLLM (opens in a new tab) project from LMSYS reported cost reductions of over 85 percent on MT Bench, 45 percent on MMLU and 35 percent on GSM8K compared with sending everything to GPT-4, while still achieving 95 percent of its performance. Earlier, the FrugalGPT (opens in a new tab) paper from Stanford showed that cascading cheaper models before an expensive one could match the best single model with up to 98 percent lower cost on its test tasks.
How to prove a small model is good enough
The risk in moving traffic to a small model is not that it fails loudly. It is that it fails quietly, with answers that look fine and are slightly worse. The only protection is measuring quality on your own requests before and after the switch.
- Build a test set from real traffic. Pull 100 to 200 recent requests for one task type, including awkward ones, and keep the large model's answers as a baseline.
- Define pass and fail in writing. For extraction, that might be exact field matches. For support answers, it might be a short rubric: correct, complete, on policy, right tone.
- Run the small model on the same inputs. Score both sets the same way. A large model can do first-pass grading against your rubric, but have a person check a sample of its judgments.
- Look at the failures, not just the score. If the small model fails on one pattern, route that pattern to the large model instead of abandoning the switch.
- Ship behind a percentage. Move 10 percent of live traffic, compare resolution, retry and escalation rates for a week, then widen.
This is also where most of the savings come from in practice. Teams rarely move a whole product to a small model. They move the three or four task types that pass cleanly, and those are usually the highest-volume ones.
Caching and batching: the two cheaper levers
Routing is not the only way to cut inference cost, and it combines well with two others that need no change in model at all.
- [Prompt caching](https://platform.claude.com/docs/en/build-with-claude/prompt-caching): if every request repeats the same long system prompt, instructions or reference document, caching that prefix means later calls read it at a fraction of the normal input price. On Anthropic's current price list, cache reads on Haiku 4.5 and Sonnet 5 are billed at one tenth of the base input rate. For context-heavy workloads like the support example above, that can matter as much as routing.
- [Batch processing](https://platform.claude.com/docs/en/build-with-claude/batch-processing): work that does not need an answer in seconds, such as nightly classification, content tagging or evaluation runs, can go through a batch API at half price on both input and output.
- Shorter context: sending only the retrieved passages a request needs, instead of whole documents, lowers cost on every tier and often improves accuracy too.
Why small models got good enough
- Distillation: smaller models trained on the outputs of larger ones, a technique formalized in Hinton, Vinyals and Dean's 2015 paper (opens in a new tab), now come close to their teachers on narrow tasks.
- Quantization: running weights at 4-bit or 8-bit precision cuts memory enough to change which hardware you need. The QLoRA (opens in a new tab) paper showed 4-bit fine-tuning can preserve full 16-bit task performance.
- Better retrieval: a small model given the right document often beats a large model answering from memory.
- Better prompts and skills: precise instructions close much of the gap. A clear prompt, like the ones in our Claude prompt engineering guide, does more for a small model than for a large one.
When not to use a small model
- The request is ambiguous and the model has to work out what the user means.
- The answer needs several dependent reasoning steps, such as planning or debugging.
- A wrong answer is costly: legal, financial or medical content, or anything that triggers a refund.
- There is no retrieved context and the task depends on broad knowledge.
- You have not measured quality yet. Start on the large model, collect examples, then move traffic down once you can prove parity.
How to start cutting LLM costs this month
- Log every request with its task type, input length and outcome, so you know your real traffic mix.
- Pick the one or two highest-volume, lowest-risk task types and test them on a small model against a sample of 100 real requests.
- Add a rules-based router and a fallback to the large model, then track cost per resolved request next to latency and error rate.
- Turn on prompt caching for shared context and batch processing for anything that can wait.
- Package repeatable instructions as reusable Claude Skills so every tier gets the same precise procedure.
The likely end state is not that small models win. It is that the question stops being interesting, the way nobody asks which database you use before asking what you store. Model choice becomes a per-endpoint decision, tracked on a dashboard next to latency and error rate. Teams that build the routing layer early do that calmly; teams that build it late do it under budget pressure. For more on the models and tools behind this, see our AI guides.